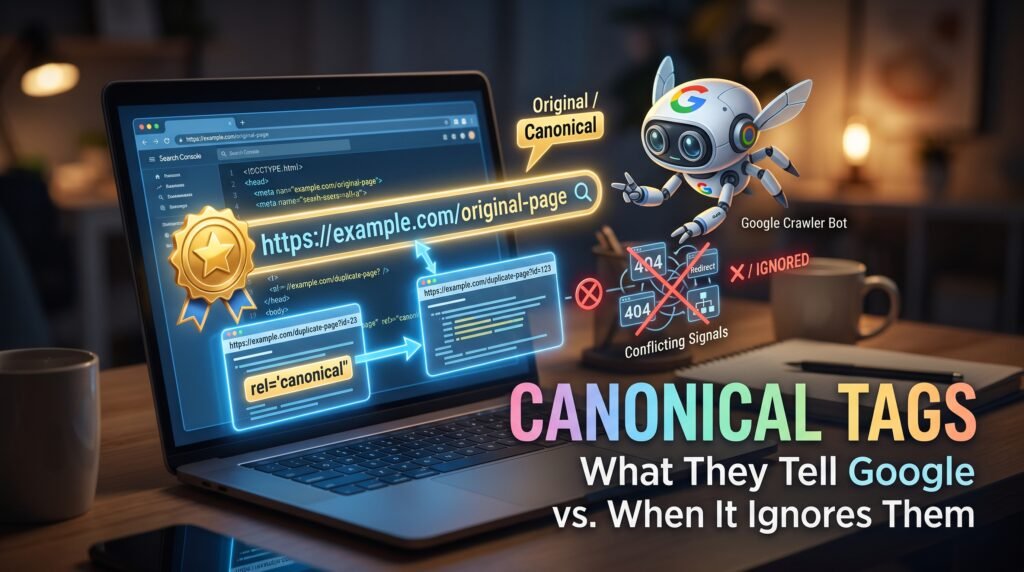
A canonical tag tells Google which version of a page you’d like treated as the main one, and Google can decide differently. Most canonical problems I’d expect to find come from conflicting signals, so the useful check is whether everything on the site agrees about which URL is the main one.
What a canonical tag is for
A canonical tag is a line in a page’s head that names the preferred URL for a page that exists at more than one address. It helps Google group duplicates, such as tracking-parameter URLs or http and https versions, and choose one to show. It doesn’t remove the other URLs.
Google’s documentation describes the process as choosing a canonical from several signals, including whether a URL is https, how it’s linked, whether it’s in the sitemap and the rel=”canonical” annotation [1]. You can state a preference with those methods, but Google may choose a different page as canonical than you did [1]. An older Search Central post uses the word “hint” directly [2].
So treat a canonical on your own site as a statement of intent, and check in Search Console which URL Google actually chose.
When Google ignores it
Google tends to ignore a canonical when the rest of the site contradicts it. If a page canonicalises to URL A but the sitemap lists URL B, every internal link points to B, and A redirects to B, the signals disagree and Google is free to choose.
Google’s documentation lists several things not to do. Don’t give the same page different canonical URLs through different methods, such as a sitemap entry and a tag. Don’t use noindex to select a canonical, because it blocks the page from Search entirely. Don’t use robots.txt for canonicalisation. Don’t let JavaScript change the canonical after the HTML sets it, and don’t put fragments in the URL [1].
An older post on common mistakes adds practical checks. The canonical target should exist and not be a soft 404, it shouldn’t carry a noindex tag, and a canonical should only point to a different page when that page genuinely replaces the first in results [3]. The post is from 2013, so I’d treat the specifics as background and the current documentation as the reference.
The mistakes I’d look for in a crawl
| Fault | What it looks like | Why it causes trouble |
|---|---|---|
| Canonical points to a redirect | The tag names a URL that 301s elsewhere | Two signals for the same page, and a wasted hop |
| Canonical points to a 404 or noindex page | The target can’t be indexed | The preferred URL isn’t a valid candidate |
| Canonical differs from the sitemap | Sitemap lists another version | Conflicting signals about the main URL |
| Relative canonicals | /page/ instead of the full address |
Google accepts them but recommends absolute URLs, partly because a crawled staging site can inherit the wrong one [1] |
| Canonical set late by JavaScript | Raw HTML and rendered HTML differ | Google advises against changing it after the HTML sets it [1] |
| Every page canonicalises to the homepage | A template or plugin setting | The pages tell Google they’re duplicates of the homepage |
The simplest way to run this is a crawl that records the canonical for every URL and compares it with the URL itself, the status code of the target and the sitemap. A self-referencing canonical on every indexable page is the normal state of a healthy site, so differences are what you’re hunting for.
Canonical, noindex and redirects are different tools
They answer different questions. A canonical says “these pages are duplicates, prefer this one”. A noindex says “don’t show this page”. A redirect says “this URL has moved”. Using one where you mean another is where many canonical problems start.
If a page shouldn’t be in search at all, noindex is the tool, and Google’s documentation advises against using it to pick a canonical [1]. If an old URL has permanently moved, a 301 redirect is the tool, and Google’s redirect documentation says a permanent redirect is used as a signal that the target should be canonical [4]. A canonical alone leaves the old URL working for visitors and still crawlable.
How to check what Google chose
The URL Inspection tool in Search Console shows the user-declared canonical alongside the one Google selected. If they differ, that’s your starting point. Search Console’s Page indexing report also has statuses for pages where Google chose a different canonical, so it’s worth reading that report alongside the inspection result.
When Google picks a different canonical, I’d first ask whether it’s wrong. If the two pages really are near duplicates, Google’s choice may be sensible. The data that would settle it is whether the page you wanted indexed has any impressions and whether the other version does.
What I’d do
Start with the sitemap. Make sure it only lists the URLs you want indexed, then check that each one canonicalises to itself, returns 200 and is linked internally. After that, deal with parameter and duplicate URLs through redirects or canonicals as fits each case.
If you’re working through a larger set of these, the technical SEO audit covers canonicals alongside indexing and redirects, and what goes wrong in a site migration shows how canonical faults appear during a move. Sitemaps and indexing covers the sitemap side.
FAQ
Is a canonical tag the same as a redirect?
No. A redirect sends visitors and crawlers from one URL to another. A canonical leaves both URLs working and tells Google which you’d prefer in results. Use a redirect when a page has moved, and a canonical when the same content legitimately exists at more than one address.
Should every page have a canonical tag?
Most indexable pages benefit from a self-referencing canonical, which names the page’s own address. It isn’t required for Google to index a page, but it removes ambiguity when the page is reachable through parameters or alternate paths.
Can Google ignore my canonical tag?
Yes. Google describes the tag as one signal among several and may choose a different canonical. It’s most likely when your sitemap, internal links or redirects point to a different version. Make those agree and Google has less reason to differ.
Can I use noindex and a canonical on the same page?
It’s best not to. They send conflicting messages, since one says to prefer another URL and the other says to keep the page out of results. Google advises against using noindex to select a canonical.
Sources
- Google Search Central, How to specify a canonical with rel=”canonical” and other methods, accessed 2 November 2026.
- Google Search Central Blog, Handling legitimate cross-domain content duplication, December 2009.
- Google Search Central Blog, 5 common mistakes with rel=canonical, April 2013.
- Google Search Central, Redirects and Google Search, accessed 2 November 2026.